

João M.
Deep Learning Research Engineer
Hän on erikoistunut rakentamaan kehittyneitä malleja, mukaan lukien suuria kielimalleja (LLM), jotka kykenevät koodinkorjaukseen, vikojen havaitsemiseen ja jatkuvaan oppimiseen. João toimii laajasti PyTorchin kanssa ja hyödyntää malleja pilvialustoilla ja korkean suorituskyvyn laskentajärjestelmissä.
Ennen ASML, hän johti tutkimusryhmien GAIPS Lab, joka on julkaistu johtava tekoälykonferensseja, ja turvattu kilpailukykyisiä avustuksia Yhdysvalloista. Ilmavoimat ja FCT. Hän opetti myös tekoälykursseja, ansaitsemalla opetus Excellence Award -palkinnon hänen panoksestaan koulutukseen.
João keskeisiä projekteja ovat jatkuvan oppimisen tekniikoiden kehittäminen, joka mahdollistaa uuden tiedon hankkimisen unohtamatta aikaisempia tehtäviä. ja tehostamalla oppimista kouluttamaan malleja entistä tehokkaammin vähemmillä tiedoilla. Hän on intohimoinen tehdessään tekoälyn järjestelmistä tehokkaampia, käytännöllisempiä ja jatkuvasti parempia.
Tärkein asiantuntemus
 Python10 vuotta
 Machine Learning10 vuotta
 Data Science10 vuotta
 Scikit-learn10 vuotta
Kokemus7
AI Researcher
Developing a production-oriented AI system for personalised patient interventions in dementia care, combining reinforcement learning with large language models. Designed and built ToneRL, a hybrid architecture where a lightweight RL agent learns to control an LLM’s output in real time, adapting communication style to individual patients based on clinical feedback, without retraining or modifying the underlying model. Collaborating directly with clinicians and linguists to ensure outputs meet clinical communication standards. The architecture is designed for scalable deployment: one frozen base model serves all patients, with per-patient adaptation handled by lightweight policy instances requiring minimal compute.
 MongoDB
 Docker
 Project Management
 Budget ManagementPython
Deep Learning Research Engineer
- Led tutkimusryhmä "LLMs for Software Engineering" -hankkeesta, jossa keskitytään velan tekniseen vähentämiseen, virheentunnistus ja dokumentaatio-analyysi käyttäen suuria kielimalleja.
- Suunniteltu, toteutettu, koulutettu, testattu, ja otettu käyttöön LLM automaattista koodin refactoring ja vikojen havaitseminen.
- Käyttöönotetut mallit pilvituotantoympäristöihin ja suurteholaskentaan jaettuihin tietotekniikkaklustereihin.
- Seurataan käytössä olevien mallien jatkuvaa suorituskykyä käyttäen esimerkiksi MLFlow-, Sacred- ja Painot & Biases-työkaluja.
- Yhtiön tutkimusosasto yhdistettiin akateemisiin kumppaneihin TU/e.
Docker Java
 FlaskPython
 C++
Deep Learning Research Engineer
- Suunnitellut, toteutettu, koulutettu, testattu ja otettu käyttöön huippuluokan syvä oppiminen arkkitehtuurit, mukaan lukien Actor-Critics, DQNs, ja LLM:t, jotka käyttävät vallankumouksellisia, toistuvia ja tarkkaavaisia mekanismeja ominaisuustietojen keräämiseksi monenlaisista tehtävistä.
- Käyttöönotetut mallit pilvipalveluiden tuotantoympäristöihin, kuten Google Cloudiin, Amazon AWS:ään ja Slurm HPC -jakeluklustereihin.
- Seurataan käytössä olevien mallien jatkuvaa suorituskykyä käyttäen esimerkiksi MLFlow-, Sacred- ja Painot & Biases-työkaluja.
- Koottiin yhtiön HPC Slurm klusteri.
- Led viisi tutkijaryhmää kuin ensimmäinen kirjailija, joka julkaisee tutkimuspaperin kunkin huipputason tekoälykohteissa, mukaan lukien AAAI, IJCAI, ECAI, Artificial Intelligence Journal ja PLoS One Journal.
- Esitetty tekoälytutkimus huipputason kansainvälisissä konferensseissa, kuten AAAI, IJCAI ja ECAI.
- Varmistettu kaksi kilpailevaa rahoitusapua, yksi Yhdysvalloista. Air Force Office of Scientific Research ja toinen Portugalin tieteen ja teknologian säätiön (FCT).
- Sai parhaan paperin palkinnon hankkeelle ”Helping People On The FLLy: Ad Hoc Teamwork for Human-Robot Teams.”
DockerPythonData Science Joomla
 NumPy
Software Engineer
- Teknisen velan väheneminen ja Top Sky Tower -ratkaisun entistä kattavampi testaus, joka on lennonjohtajien työkalu elektronisten nauhojen hallintaan.
- Toteutettu ja testattu kriittisen turvallisuuden havaitsemisjärjestelmät.
JavaC++ C#
 WPF
Software Engineer
- Koulutettu Convolutional Neural Network luokitella voimassa olevat henkilökorttikuvia.
- Toteutettu ohjelmisto AWS pilven AWS -tietojen automaattiseen ja ajoittaiseen varmuuskopiointiin.
- Uudelleentoteutetut perinteiset ohjelmistot, joissa käytetään nykyaikaisia teknologioita, kuten Scala ja Kotlin.
JavaPython AWS S3
 Scala
 Kotlin
Software Engineer
• Implemented graphical user interfaces using WPF and .NET for the trading team • Refactored and optimized code in several legacy projects, increasing overall performance of proprietary trading tools by up to 30%
JavaC++C# .NETWPF
Laravel Developer
Designed and developed a website for the Trainees project - matchmaking companies and near-graduates from the Portuguese ESHTE
 PHP
 Laravel
 MySQL
 MariaDBMongoDBDocker
Tekniikan huippuosaaminen
Kaikki Deep Learning Research Engineert, jotka ovat hakeneet Proxifylle, pisteytetään välillä 0–300 insinööritaidon perusteella, joka on yksi viidestä arvioimastamme parametrista. Tämä pistemäärä heijastaa ainoastaan insinööritaitoa, perustuen haastatteluihin, kotitehtäviin, suorissa koodausistunnoissa sekä työn suorituskyvyn arvioinnissa annettuihin tuloksiin. Kaavio näyttää, miten kaikki arvioidut Deep Learning Research Engineert jakautuvat tässä mittakaavassa, hyväksymisrajamme tälle parametrille sekä missä kohtaa João sijaitsee.
Score 180 · Top 14% of engineers
Portfolio
Korostanut João
 1
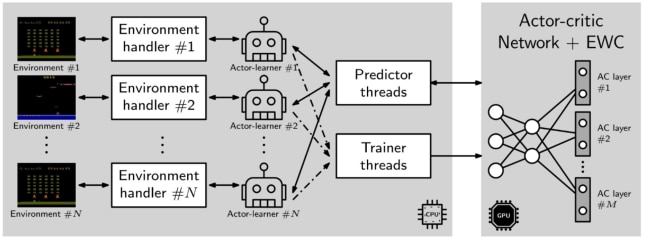
This project investigates two hypothesis regarding the use of deep reinforcement learning in multiple tasks. The first hypothesis is driven by the question of whether a deep reinforcement learning algorithm, trained on two similar tasks, is able to outperform two single-task, individually trained algorithms, by more efficiently learning a new, similar task, that none of the three algorithms has encountered before. The second hypothesis is driven by the question of whether the same multi-task deep RL algorithm, trained on two similar tasks and augmented with elastic weight consolidation (EWC), is able to retain similar performance on the new task, as a similar algorithm without EWC, whilst being able to overcome catastrophic forgetting in the two previous tasks. We show that a multi-task Asynchronous Advantage Actor-Critic (GA3C) algorithm, trained on Space Invaders and Demon Attack, is in fact able to outperform two single-tasks GA3C versions, trained individually for each single-task, when evaluated on a new, third task—namely, Phoenix.
We also show that, when training two trained multi-task GA3C algorithms on the third task, if one is augmented with EWC, it is not only able to achieve similar performance on the new task, but also capable of overcoming a substantial amount of catastrophic forgetting on the two previous tasks.
Muut projektit 3

Koulutus


Lopeta selaaminen.
Sovitetaan nopeammin.
Keskustele asiantuntijan kanssa ja saat räätälöityjä ehdotuksia verkostostamme vain 2 päivässä.
Pääsy yli 6 000+ asiantuntijaa
Löydä kehittäjä keskimäärin 2 päivässä
Palkkaa nopeasti ja helposti 94% onnistuneella osumalla